Scaling World-Model Reinforcement Learning Through Diffusion Policy Optimization
arXiv:2605.26282, 2026
* Equal contribution (core contributors). † Corresponding authors.
Overview
Model-Based Diffusion Policy Optimization (MBDPO) addresses the mismatch between search and value learning that limits the scaling of world-model reinforcement learning. It unifies search and policy optimization through a diffusion policy in a learned latent world model, using model-based returns to guide denoising and an implicit energy function to anchor the policy to the behavior distribution. The work studies multi-task offline pretraining, online learning, and offline-to-online fine-tuning, with consistent performance gains as model capacity increases.
Resources
Framework
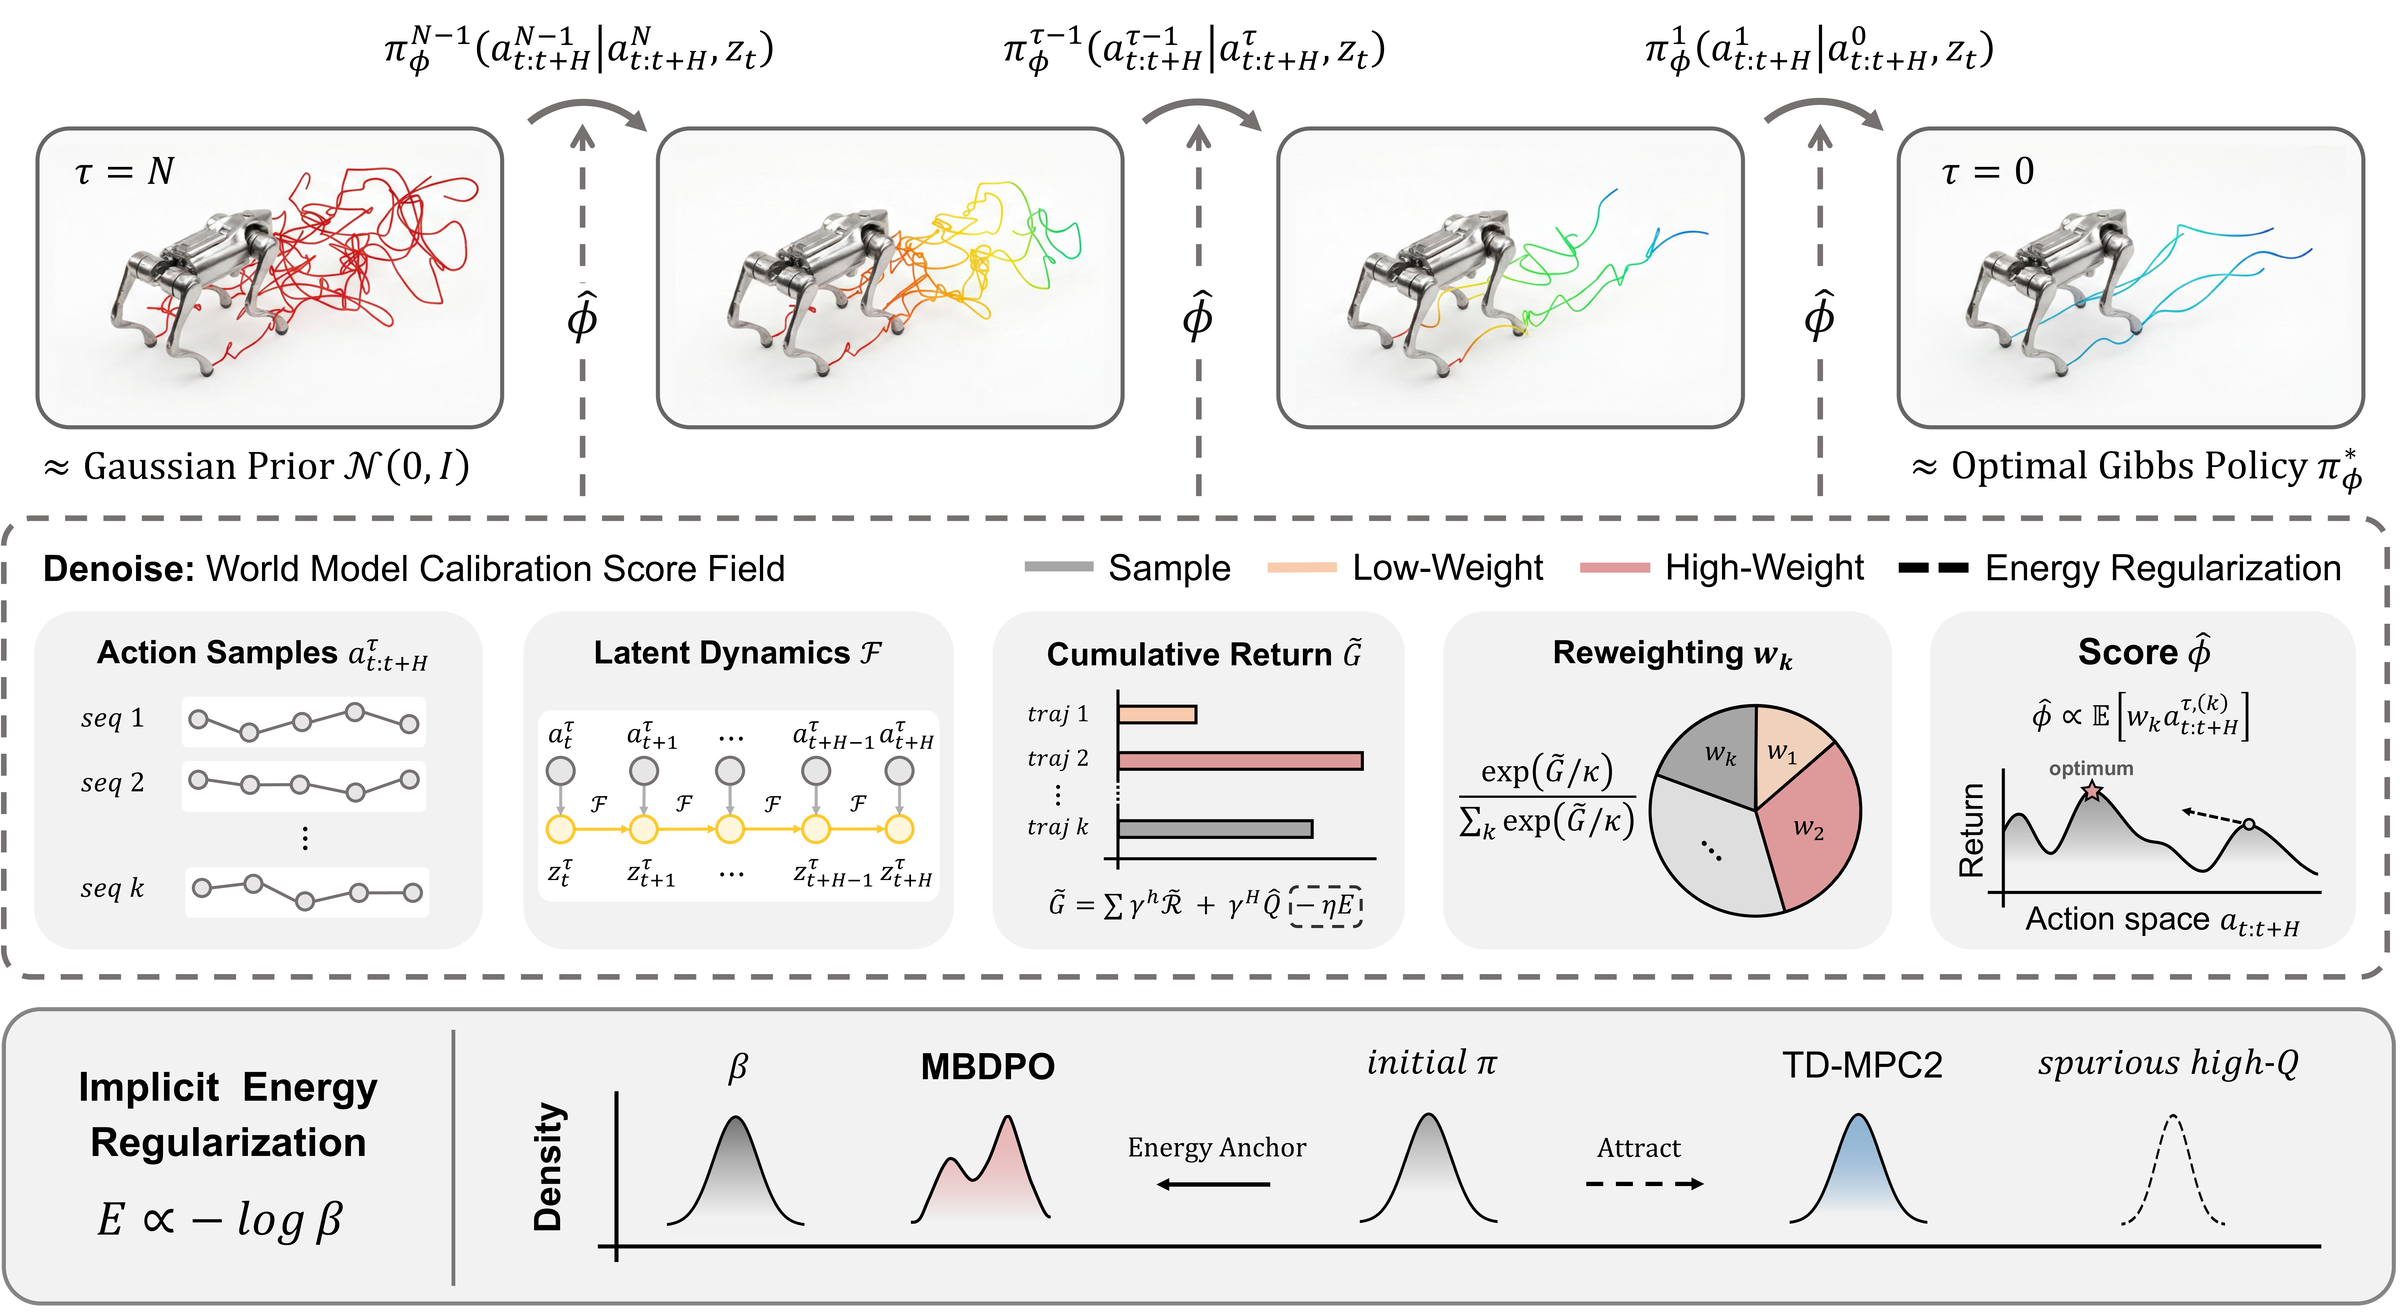
MBDPO framework, from the project page.
Citation
@misc{cheng2026scalingworldmodelreinforcementlearning,
  title = {Scaling World-Model Reinforcement Learning Through Diffusion Policy Optimization},
  author = {Xiaoyuan Cheng and Wenxuan Yuan and Zhancun Mu and Yuanzhao Zhang and Yiming Yang and Hai Wang and Zhuo Sun and Che Liu},
  year = {2026},
  eprint = {2605.26282},
  archivePrefix = {arXiv},
  primaryClass = {cs.LG},
  url = {https://arxiv.org/abs/2605.26282}
}